Running all-bound as one motion, not five separate teams
Most companies running top of funnel today are running five separate motions that happen to share a logo. Paid ads target whoever the platform thinks looks like a buyer. Outbound emails a list somebody pulled six weeks ago. A sales rep cold calls a different list. Content gets published and hopes. Nobody on any of those four teams knows what the other three did to the same account last week.
All-bound is not a fifth motion. It is the same budget, the same accounts and the same signals, run as one coordinated push instead of four uncoordinated ones. Every channel points at the same target list, every touch is scored against the same criteria, and the expensive channels only fire on the accounts that have earned them.
What follows is the method, in the order we actually run it. The numbers in the lead research section are from a campaign we built this way earlier this year, into a specialist services category. We have kept the client and the category out of it, and left every measurement in.
Start with the right companies, not the right list
All-bound starts before targeting, at sourcing. Where do you find companies that are plausibly in market today? A LinkedIn export, a Crunchbase fundraising list, a set of job postings, a Google Maps export of every business in a category and a city. None of these is the right answer on its own. Over five years we have pulled qualified companies from more than a hundred different sources, and the source that works changes by industry, by geography and by what signal you are actually chasing.
The point of a source is the signal sitting inside it. A company that just raised a Series A is signalling budget. A company hiring three data engineers is signalling a specific kind of build. A company that showed up at a trade show booth is signalling category interest. Pick sources for the signal, not for how easy the export is.
One source deserves singling out, because it is the one most teams skip: job postings. They are the only public source that gives you the account, the timing and the exact gap the company cannot fill, all three at once. On the campaign above, the hiring signal was what separated a company with a real problem this quarter from a company that merely fit the profile. If you only build one source properly, build that one.
Qualify the companies deeply, before anything else
If you get the right company at the right time into the funnel, that is fifty percent of the campaign won already. Everything downstream, every email, every ad, every call, goes wrong if this step is wrong, because you are optimising the wrong target.
Qualification should run on hard data, not a hunch. How many white collar employees does the company have, using LinkedIn headcount as a proxy? How big is the specific department you sell into, using a department-level search in Apollo or Prospeo? How many people carry a specific term in their job title today? None of this needs judgement. It is a filter on a spreadsheet or a database, and any coding assistant can build the automation that runs it.
The discipline is to write the filters down as numbers before you run them, so the list cannot be argued with afterwards. On the campaign above, two filters did nearly all the work and took the starting list from around 300 companies to 120:
- Does the company actually hold the thing we sell into, or does it sell software to people who do? Roughly 30 percent of every list in that category was the wrong business model entirely, and it is checkable in code from the company's own site.
- Is this a real operator in the category, or a general services shop that added the category to its menu? The qualifier was whether the company is hiring for it right now, or publishes a team size for it. Both are facts, neither needs a model.
Expect to lose more than half the list, and treat that as the step working. A starting list of 120 to 150 companies surviving down to about 100 qualified is a healthy ratio. A list that barely shrinks means your filters are decorative.
Save the thinking for choosing the criteria, not for running them four thousand times. The intelligence belongs once, at design time. Everything after that is arithmetic.
Finding the right people is where campaigns are won and lost
Once the company list is qualified, the harder problem starts: who inside each company actually matters. This is the part that looks simple and is not. It took five years of trying to teach it to a team, and two days inside code that kept producing lists that looked right and performed badly, before it turned into something repeatable enough to write down.
The mistake almost everyone makes is starting from a list of job titles they wrote down in a meeting. Your buyers do not use your vocabulary. The method below reverse-engineers their vocabulary from real profiles instead, and then scales it.
Step 1. Write one sentence describing a good lead
Not a department, not a seniority band. One sentence naming what the person is accountable for. On the campaign above it was: the person has to be directly accountable for finding people and delivering projects to clients, or is so senior that this becomes their problem.
Two things make that sentence work. It names accountability rather than a function, so it survives companies that organise differently from each other. And the "or so senior" clause catches the founder of a forty-person company who does the job personally. Every keyword you later keep or kill gets judged against this sentence, so a vague sentence produces a vague campaign.
Step 2. Pull the senior population of 10 to 15 sample companies
Take a sample of already-qualified companies and pull everyone senior, department-wide, with no title filter at all. On the campaign above this returned 609 people holding 493 distinct job titles. You are not trying to find leads yet. You are building the evidence base that tells you what the titles actually are.
One trap here costs you the whole exercise if you miss it: check what each sample company actually resolved to. Data providers hand back the wrong company roughly a quarter of the time and say nothing about it. We had a seed resolve to an unrelated business and return three gig workers, and every keyword mined from it would have been poisoned. Seed on the domain the staff use, never the one a contractor workforce signs up on.
Step 3. Classify every distinct title into three buckets, not two
Relevant, maybe relevant, not relevant. The binary version of this kills real leads: titles like "VP, Central Ops" and "Head of Ops Planning and Excellence" get rejected on the title alone and never reach a profile read, when in some companies they are the entire buying centre.
A title nobody can call from the title alone is a routing decision, not a rejection. Maybe relevant costs you one profile lookup, around two cents. A missed lead is gone for good. That asymmetry is the whole argument for the third bucket.
Step 4. Score the people, not the titles
Pull the full public LinkedIn profile of everyone in the relevant and maybe-relevant buckets, and score each one for lead relevance, an LRS from 0 to 100. The inputs are the current title, past titles at this company, past titles at other companies, the self-written job description, the about section, the headline, and where it adds signal, education and key skills.
Three design choices matter more than the model you use:
- Have the model return facts, not the score. Does this person own a team that does the thing? Do they name a workforce they are accountable for? How long in seat? How senior relative to company size? Then let code turn those facts into the number with fixed weights. A model's 49 against its 51 is noise, and the cutoff has to mean something. Changing a weight re-scores everyone for free instead of re-reading thousands of profiles, and the reason writes itself out of the facts, so every score is auditable.
- Check the person still works there before you spend anything on them, in code, before the model call. Provider career history is a snapshot and goes stale. Two leads in the first run had left months earlier and still showed as current. Write the live job title back too: one lead had been promoted from SVP to Chief Business Officer and the provider still had the old title.
- Score once per person, ever, and cache it. This is the step that costs money, so it should never run twice on the same human being.
Of the 609 people in that sample, 372 scored as genuinely good leads. That is 61 percent, from a population that on titles alone looked far more promising than that.
Step 5. Mine the keywords from the people who scored well
This is the step that compounds. Take everyone who scored well and find which words recur in their job titles. You are no longer guessing at your buyers' vocabulary, you are reading it off people you have already verified.
Keep a keyword only if it passes two tests, and the second one is the one everybody skips:
- Precision. At least 90 percent of the people it catches are good leads. On that campaign, "delivery" caught 22 people and 22 were good. "Operations" caught 71 and 68 were good, 96 percent. "Staff" caught 13 out of 13, because in this category Chief of Staff is a real buyer.
- It appears in at least two sample companies. A sample is always dominated by its largest company, 47 percent of ours came from one, and without this test that single company's internal naming quietly becomes the filter for the entire campaign.
The guardrails matter as much as the keeps, and they are not the obvious words. Here is what actually failed the bar on that campaign, with the real numbers:
- "data" — caught 20 people, 16 good, 80 percent. It pulls in Head of Data Engineering and Head of Database Administration, who build systems rather than own the outcome.
- "ceo" and "chief executive officer" — 85 and 86 percent. The failure is not the CEO, it is "Executive Assistant to the CEO" and "Senior Manager, Executive Assistant to the CEO". Search the title for "founder" and handle chief executives in the catch-all instead.
- "program" — 83 percent, because Director of Program Management, GTM is a different job. "services" — 83 percent, undone by India Head of HR and Shared Services. "head of growth" — 82 percent, undone by Head of Growth Marketing. "product management" and "intelligence" — 80 percent each.
Notice that none of these are the generic words people warn you about. They are plausible, on-category words that fail for a specific structural reason, and you only find out which by measuring. That is the argument for doing steps 2 to 4 before you write a single keyword down.
One refinement worth the effort: a broad word that fails on its own often works as a compound. "Operations" alone was fine here, but where a word like it fails, its good titles usually share a second word. "Account director", "acquisition head", "AI product director" each hold only one or two people, so frequency mining never proposes them, and in a specialist category they are the best-fitting roles on the list.
Step 6. Run two searches, not one
Your keyword search will miss people, and you should know exactly who. On that campaign, 96 good people held titles containing none of the include keywords: 16 chief executives, 12 in product development, 8 in AI and machine learning, and a long tail of country heads and chiefs of staff whose titles carry no category vocabulary at all.
So freeze two searches. Search one is the keyword search. Search two is department plus seniority with every search-one keyword in the exclude box, which catches exactly those 96 and guarantees the two sets never overlap. Run both pooled across the full company list rather than looping company by company, then score the results with the same LRS pass and cap in code.
Our cap scales with company size, measured on raw LinkedIn headcount: over 1,000 staff takes 15 leads, 500 to 1,000 takes 10, under 500 takes 5. Anyone scoring 90 or above is exempt and always goes through, even past the cap, so a company with 20 outstanding people sends all 20. The cap only applies to the middle band. Everyone cut is flagged with a reason rather than deleted, because next quarter you will want to know why.
The economics are the reason the whole structure exists. Reading every profile at 29 accounts costs about fifteen dollars and the keyword work looks like wasted effort at that size. At several hundred accounts, reading everyone runs into the hundreds of dollars. The keyword buckets are the artefact that makes the scaling step affordable, and steps 2 to 5 exist to build them on evidence instead of on guesses.
No lead gets contacted on the strength of its job title, however perfect the keyword match. The score is the final gate, always. That is precisely what lets the keyword filter stay generous — a wrongly included person costs two cents, a missed one is lost forever.
Sequence the channels by cost, not by preference
With a scored list of companies and people, the next problem is sequencing. All-bound treats channel as a cost ladder, not a menu. Cheap channels run wide, on everyone. Expensive channels run narrow, only on whoever the score says has earned them. Getting that ladder right, not any single channel, is what separates all-bound from a company just running four things at once.
Roughly, and it varies by market: email runs to a few cents per person per month, which is why it can carry your whole qualified list. LinkedIn costs a seat plus a hard daily cap on actions. A cold call costs a trained human being several minutes. The ordering below follows directly from that.
Ads, as air cover
LinkedIn ads, Google search ads and awareness emails exist to keep your name in front of the account while the expensive channels do the real work. They are not expected to close. Target only the accounts already on your qualified list, because platform lookalike targeting is the exact opposite of account-first: it goes wide on a guess instead of narrow on a list you have already qualified. Cost per impression is low enough that this is the one channel where reach can run ahead of the score rather than being gated by it.
Cold email, as volume
The volume channel, sequenced across a large pool of sending domains and inboxes at a volume no single domain could carry without being flagged. Build the sending infrastructure to be replaced rather than protected: at this volume a burned domain is a cost of doing business, not an emergency. Because the per-person cost is so low, this is the channel that runs on the entire qualified list rather than a scored subset.
LinkedIn, for the people who never open email
Connection request first, then a message once they accept. It has to be paced to look like a person sending it, which caps daily volume and means list quality matters more here than anywhere else, not less. Use Dripify or HeyReach for the sending mechanics, but the score still decides who gets a connection request today. A tool that can send does not mean everyone should receive one at the same rate.
Cold calls, and the part nobody budgets for
The highest reply rate of the four by a distance, and the easiest to get wrong. Reserve it for the accounts your score has already marked as worth the cost. Enablement matters more than tooling here: a rep who is not coached weekly is being set up to fail. Thirty minutes of mock calling every week, and thirty minutes breaking down a real call recording every week, without exception.
One thing from experience that costs teams more than any tool choice. A shared rep who is also selling something else for another team will rarely reach the depth of understanding your offer needs. The skill compounds daily or it does not compound at all. Where you can, give the motion a dedicated rep whose only job, day in and day out, is that one thing.
Every all-bound motion needs an offer
None of the targeting or sequencing above matters if there is nothing worth saying once you reach the right person. An offer is something you add to your outreach, an email, a LinkedIn DM, an ad, that gets a prospect to raise their hand and tell you they are worth investing time in. The test that separates a real offer from a sales pitch in disguise: would they still want it if they never bought from you? If the answer is no, it is a pitch wearing an offer's clothes.
There are nine broad types worth knowing before you invent your own: value-delivery (a tool or template they keep), risk-removal (you absorb the downside, pay per meeting, walk away anytime), exclusive access (a real, small cohort), insight or research (data specific enough to read as original), a free product, a done-for-you sample, a diagnostic or audit, a peer benchmark, and a co-built asset you build with them in one working session. Most companies only ever need one or two of these working well, not all nine at once.
Placement matters as much as the offer itself. In cold email, the large majority of replies come to the first message in the sequence, so the offer belongs in email one, not buried three follow-ups in as an afterthought once the pitch has already failed to land. And once you have an offer that works, package it like one: give it a name, put it on its own page, and treat it as a real asset rather than a line item in a longer message. We wrote the full framework, all nine types with worked examples and the design principles behind each, in Side Kick's offer creation framework if you want to build your own.
Run it as experiments, because you are looking for one play
The entire point of all-bound is to find one play, the specific mix of targeting, messaging and channel, that drives predictable meetings. Once you find it, it should scale to nearly any revenue number you need.
Finding it takes 3 to 12 months of controlled experiments, with 12 being the more honest number for most companies. And even with 12 months of focused effort, outbound fails outright for 20 to 30 percent of companies. I don't fully know why, and I would rather say that plainly than sell you a version of this with the failure rate taken out. We have written the long version of that argument in what outbound actually costs, and how to tell if it will work for you.
What separates 3 months from 12 is planning, not budget and not headcount. There are only three levers in the entire system: targeting, messaging and channel. You do not need ten plays that work, you need one that works predictably, and most companies never find it for the same reason. They change the list, rewrite the copy and add a channel in the same month, reply rates move, and nobody can say which change did it.
The discipline is to run several versions of one variable at once, targeting or messaging or channel, never two together, against slices of the list sized before the send so the result is a real answer rather than a hopeful reading of nine replies. Whichever version wins takes the volume. The rest get retired and written down, so nobody proposes them again in six months. Then the next variable gets tested against whatever is now the weakest part of the sequence.
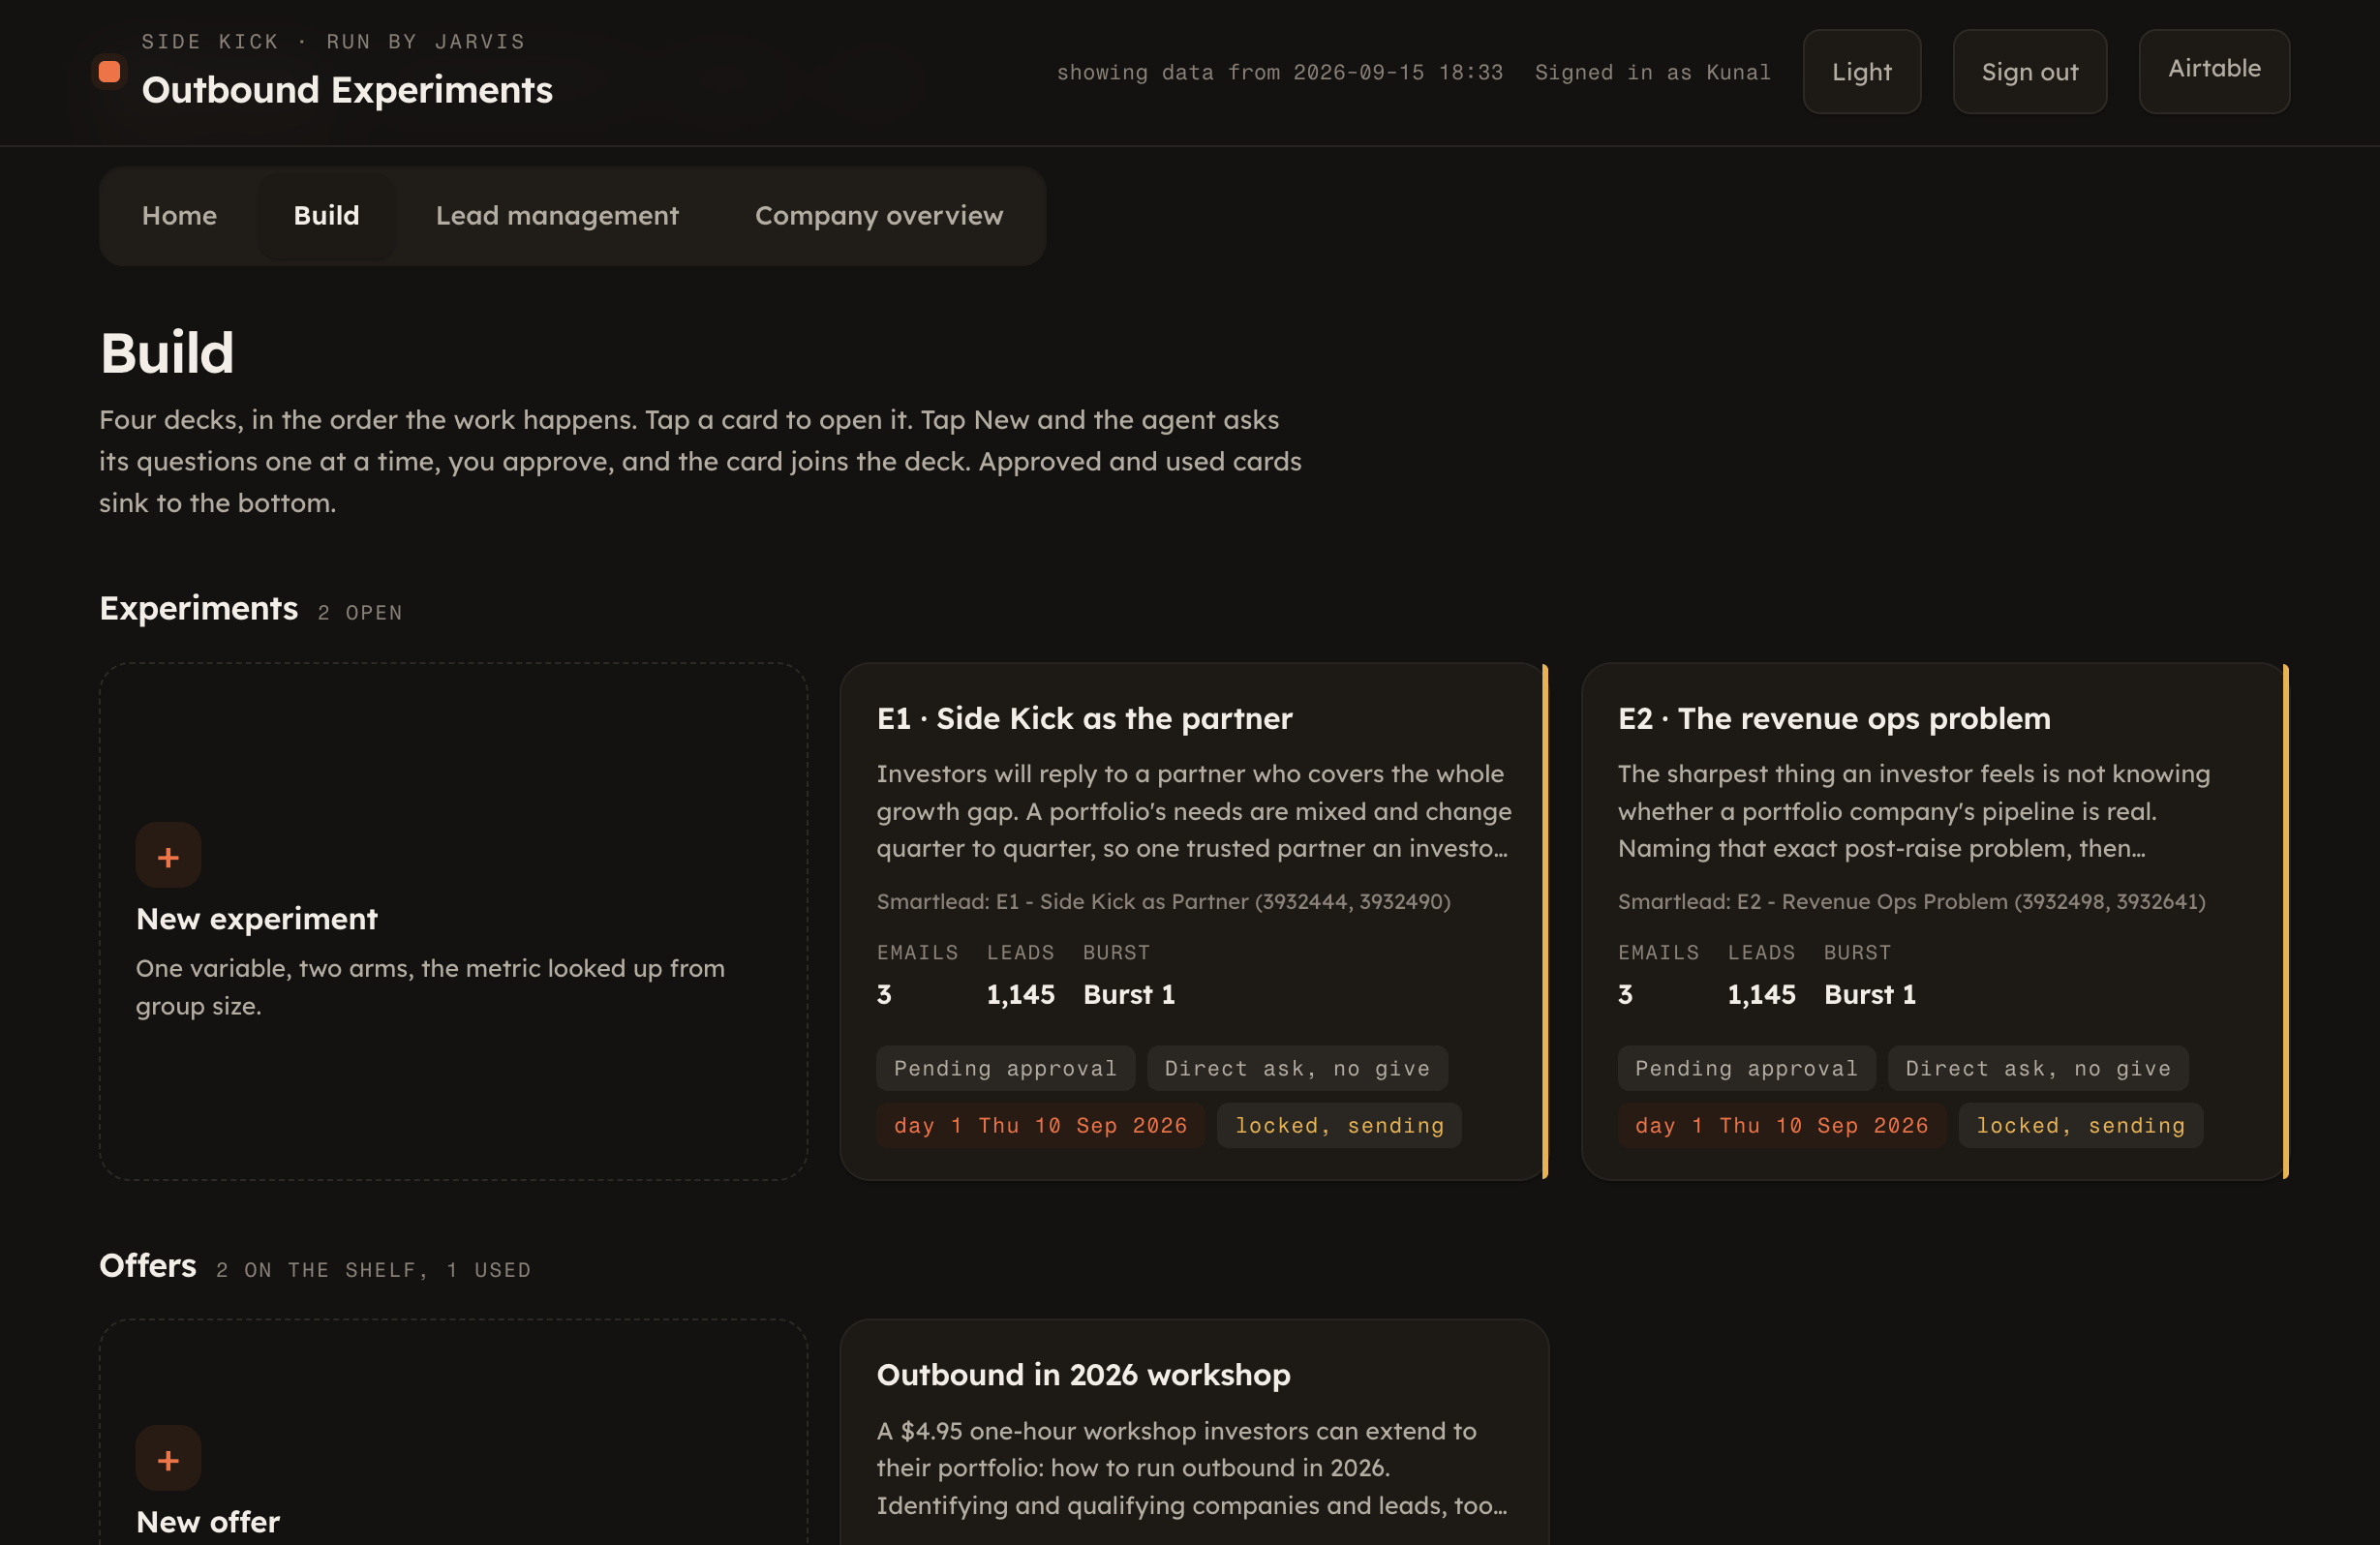
Concretely: two genuinely different offers, not two versions of the same sentence, run head to head roughly every forty-five days. Two genuinely different targeting hypotheses, not two filters on the same list, tested the same way, sometimes off a scraped source nobody else thought to build. Whether a second channel, LinkedIn on top of email, actually earns the time it costs is itself a question with a real, testable answer rather than something to assume either way. We run this exact loop as a service and go into more of the mechanics on our outbound experiments page.
Close the loop: de-anonymise the traffic you are already paying for
This is the section most teams treat as an afterthought, and it is the one that makes everything above compound. If you are running all-bound well, you are spending real money sending the right people to pages you own: landing pages, blog posts, case studies, white papers, tools. Every one of those visits is a buying signal from an account you have already qualified. Left anonymous, you paid for the signal and then threw it away.
Run inbound-led outbound alongside everything else. De-anonymise website visitors by IP address to find which company they belong to, and compare that against your target account list. A match raises the score, which means that account gets LinkedIn connections and calls more often than one that has shown no signal at all. This is the mechanism that lets your cheap channels decide where your expensive channels go, which is the whole idea of all-bound stated in one sentence.
Then convert every link you send into a UTM-tracked link. That is how you know the person on your site right now is John Smith from Acme, that he has spent three minutes on the case study, and what he looked at next. Drop a cookie while he is there, and the next time he returns from any other source, even a plain Google search, you still know it is him. That feeds the score too.
Done properly, the loop closes: ads and email drive the right accounts to your pages, the pages report back who showed up and what they read, the score moves, and your rep calls the account that was on your case study page on Tuesday rather than the next name on an alphabetical list. Five separate teams cannot do that, because the signal dies in the gap between them. That is the real argument for running it as one motion.
How we would run an all-bound campaign in 2026
Source for signal, not convenience. Qualify companies on hard numbers you wrote down in advance. Build the lead list by reading real people before you write a single job title down. Sequence channels by what they cost. Lead with an offer they would want even if they never bought from you. Change one variable at a time. And close the loop by de-anonymising the traffic you already paid to create.
All of it pointed at one list, scored once, shared by every channel. Not five teams optimising in isolation.
If you would rather Side Kick run this end to end
This is close to Side Kick's oldest service, and the pieces above map to a specific team, not a slide.
Sanya Deshmukh runs Google search and LinkedIn ads, and every campaign she runs targets only the shortlisted accounts. We are account first throughout: we find the right accounts before anything else runs, and nothing runs against anyone outside that list.
Gagandeep Sahni leads outbound experiments. His team builds the email and LinkedIn infrastructure, works the offer with you, and runs cold email and LinkedIn outreach as controlled experiments inside Side Kick's existing experiment harness, one variable changed at a time so you can tell what actually moved the number.
Depending on your annual contract value, the effort routes to either a Zoom meeting or an in-person round table. Round tables are led by Seema Vacchani, who runs every event-based project at Side Kick, with sales reps available through our partnership with School of SDR, who we have run multiple projects with and rate highly.
If any of this sounds like the gap in your own funnel, read what outbound actually costs and what we look for in a target account before you talk to us. Book a call with Side Kick to talk through whether this fits your GTM.